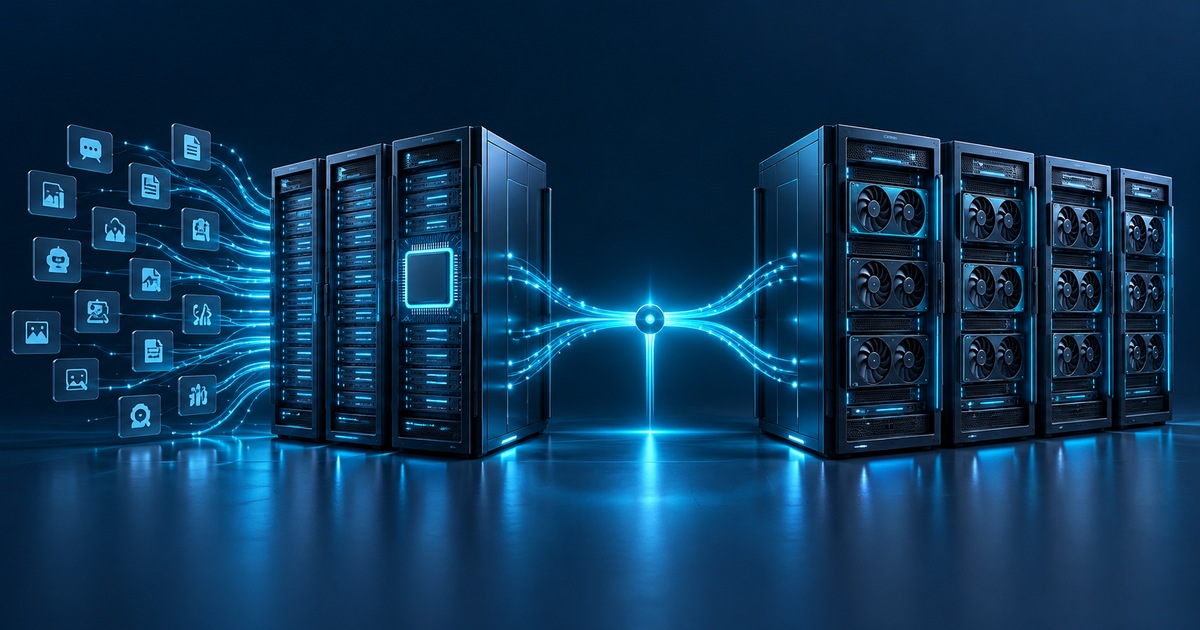
On 12 October 2026, AMD introduced Helion, an open rack blueprint for AI agents. The company describes CPU configurations linked to separate model-inference infrastructure and combined CPU/GPU versions. An integrated router directs model calls, with partner availability planned for November. This is an announced architecture under development, rather than evidence of a system already deployed for every customer. AMD announcement.
An agent's work is more than one operation
Our editorial reading is that infrastructure should follow the entire workflow. Consider a hypothetical agent preparing a report from internal documents. It checks the user's permissions, locates files, extracts text, sends some of that text to a model and formats the result. Between these operations it may wait for a database, a network service or human approval. This example explains the problem; it is not a Helion benchmark performed by SIExpo.
Measuring only answer-generation speed misses the time before and after generation. A fast model can sit behind a slow service when the document-processing queue is overloaded. Conversely, adding processor capacity will not accelerate a task waiting for an unavailable external interface. Monitoring each stage separately therefore has practical value: optimization should begin where the delay actually accumulates, rather than where the most impressive hardware specification happens to be.
What open infrastructure means
The Open Compute Project's Rack and Power project provides useful context. It covers rack construction, power conversion and distribution, and interfaces to cooling. Such specifications help establish a common foundation for equipment. By themselves, they do not define application behavior, agent permissions or the quality of model-generated answers. Those remain separate engineering concerns above the physical infrastructure layer.
For a team planning a deployment, this creates two distinct jobs. The first is checking whether the hardware fits the facility and its maintenance arrangements. The second is making the application use that capacity reliably. A suitable rack does not remove the need to reserve capacity, limit concurrent tasks or establish predictable recovery after an interruption. Procurement and application design need to meet at these operational boundaries.
From resources to a completed task
The Kubernetes resource-management documentation distinguishes resource requests from limits. Requests inform scheduling; limits establish usage boundaries. This is general infrastructure context, not a claim that Helion requires a particular Kubernetes configuration or that the announcement validates a customer's existing cluster.
Our practical conclusion is to separate groups of tasks with different behavior. Document extraction, model calls and final writes can have their own queues and monitoring. A large import should then be less likely to displace interactive responses indiscriminately. That separation also requires a shared task identifier. Without it, an operator can see several healthy components while still being unable to explain why the person using the service is waiting.
Routing between models adds a product decision. In a hypothetical enterprise service, inexpensive processing of short text and analysis of confidential material may follow different rules. Selection should account for permitted recipients of the data and the required result quality. The existence of a router does not demonstrate that these policies are correctly configured, or that replacing one model with another preserves the application's behavior.
How we would evaluate a deployment
For a pilot, we would compare successfully completed tasks, time to a useful result and resources consumed across the whole process. We would also record retries, failed external calls and cases needing human intervention. This avoids calling a system more efficient merely because it produces more text, including text that someone subsequently has to correct. The operational outcome is the meaningful unit of comparison.
Concrete questions remain before a purchase or migration: which configurations are actually available, how software is updated, what support covers and how unfinished work is recovered. For an architecture team, the announcement is a starting point for asking those questions. Assessment of a particular installation should rest on its own workload and measurements, while the advertised availability date should be checked again when arranging a real delivery.
Sources checked: 2026-10-12T16:32:59+00:00. Cover: AI illustration, not a documentary photograph.