On 12 October, HCLTech announced a Global Premier Partnership with Anthropic. It plans a dedicated business unit and center of excellence, with Claude and Claude Code integrations in selected products and AI Force. The announcement names AppScan and BigFix and describes human oversight for high-impact changes. This is an implementation plan, not demonstrated universal effectiveness.
Integration is its own problem
Our editorial reading is that an enterprise agent must operate within an existing process rather than merely provide a good answer. An IT support system has permissions, change history and different owners. Connecting a model does not automatically establish who may apply a fix or who is responsible if that fix creates another problem.
What the named products do
AppScan describes application testing through static, dynamic and other approaches, including component and API analysis. Its product documentation includes fix recommendations and access to findings through MCP. These capabilities explain why connecting an agent might be useful; they do not establish that the newly announced partnership has already shipped every particular new feature.
BigFix is presented as an endpoint-management platform covering inventory, configurations, patches and operational procedures. That is a different context from scanning application code. In one workflow, an agent encounters a vulnerability finding; in the other, it may reach a system able to apply changes to devices. That difference in consequences is why we consider permissions and approvals part of the functionality itself.
Anthropic's secure-deployment documentation discusses isolation, network and filesystem restrictions, request validation and least privilege. It describes tradeoffs between containers and virtual machines. No layer supplies an automatic guarantee: its significance depends on configuration and on the threats it needs to address.
A verifiable workflow
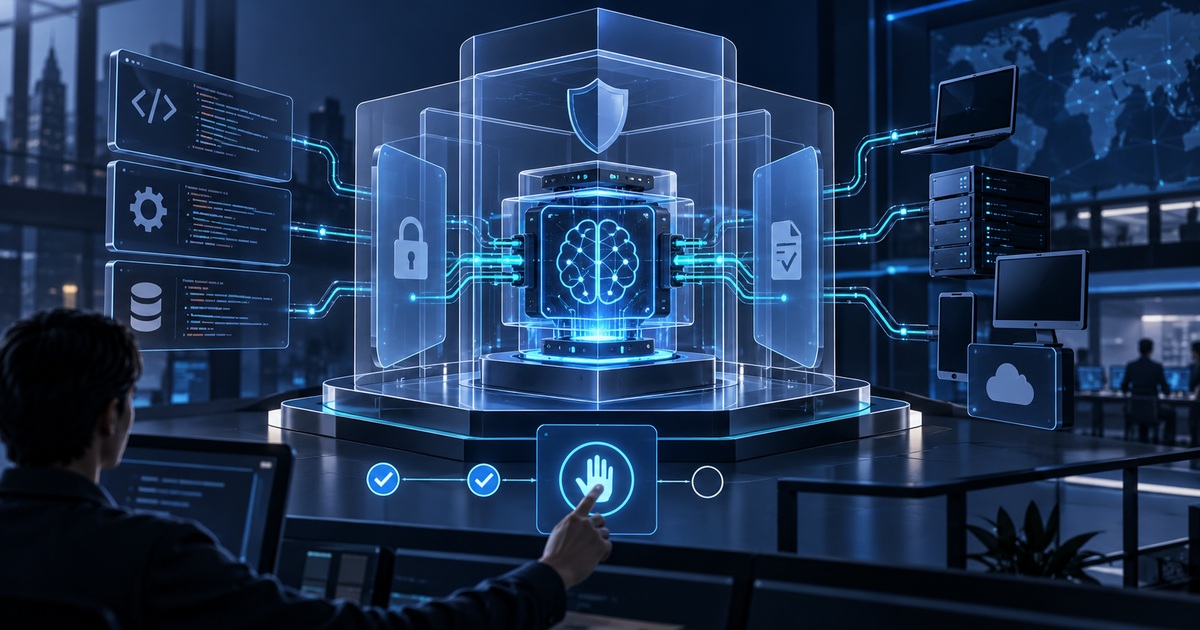
The following is an editorial example, not a reported customer deployment. An agent receives a scan finding, proposes a specific change, runs tests in a restricted environment and prepares a package for review. Following approval, only the selected change is applied, with a record of what happened and why. Success can then be compared with predefined criteria: whether the vulnerability was corrected and whether the application still works.
That example also makes failures visible. A plausible patch that fails a test remains a proposal, not a finished remediation. An approved operation that cannot be completed needs a recorded outcome, not a reassuring summary. These are the evaluation criteria we would want to see in any deployment; they are not additional results claimed for this partnership.
Our assessment is that measurable stages distinguish a useful implementation from a broad promise of autonomy. The partnership matters because it connects model technology with enterprise integration. Its impact still needs to be established through particular products, customers and checks. SIExpo has not tested these integrations and does not present security promises as independently demonstrated outcomes. The verified news is the agreement and its stated scope, with the operational results still to come.
Sources checked on 13 October 2026. Availability and prices reflect the time of verification. The cover is an AI illustration, not a photograph of an actual event.
Editorial verification (UTC): 2026-10-13T06:10:05.979402+00:00