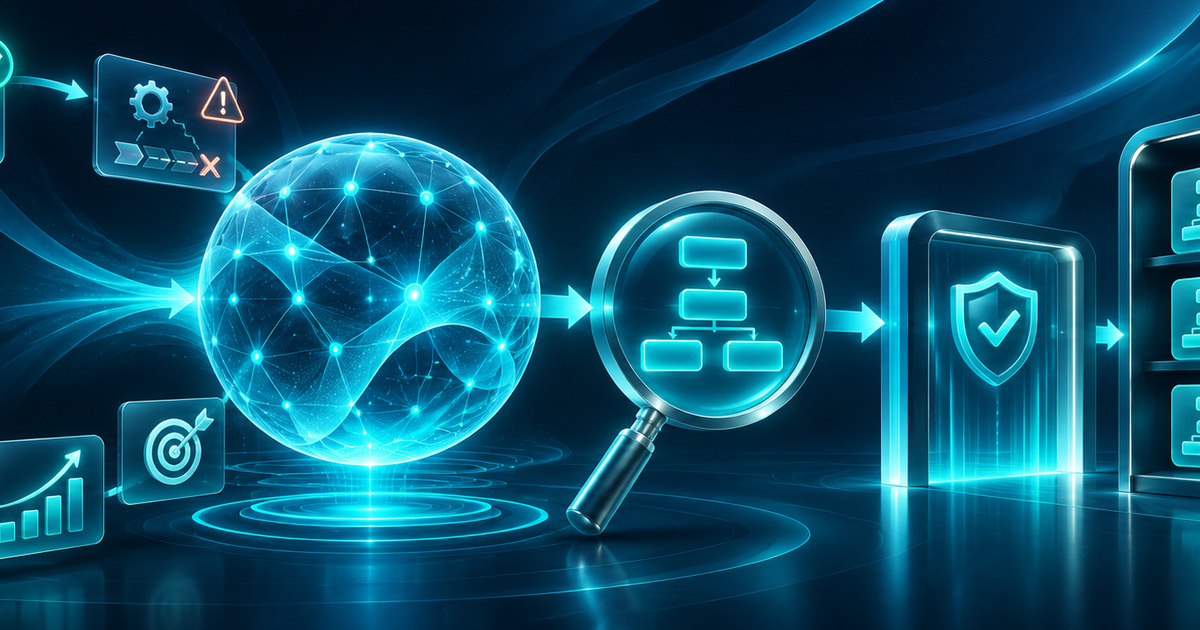
Perplexity described an extension of Brain for creating and updating agent skills from previous work on November 18. Personalization changes instructions and context rather than the underlying model’s weights. The company outlines an evidence, proposal, verification and activation loop. For shared built-in skills, candidates undergo replay checks and human review before becoming the active version.
Memory and procedure serve different purposes
The open Agent Skills format describes a skill as a folder containing SKILL.md, potentially accompanied by scripts, references or templates. A name and description support discovery, while detailed instructions are loaded when needed. This provides technical context for procedural knowledge; it is not evidence that Perplexity’s particular implementation works flawlessly.
Consider a hypothetical weekly report. Memory records which indicators matter to its reader; a procedure describes how to find, compare and present them. Mixing those roles can leave an agent remembering a preference while still omitting the check that makes the output usable. This is our editorial example rather than a reported Brain test.
One correction can create another problem
Suppose a report repeatedly omits the date of its latest update. Adding a date-checking step is a reasonable improvement candidate. But an instruction to always use the newest file could be wrong when the task requires a specific historical version. A useful procedure must preserve that exception instead of turning one successful correction into an unconditional rule.
For a comparable local process, we would look for evidence of the actual omission, a small and clearly described change, and examples against which to evaluate it. Previously successful cases are particularly valuable. They help reveal whether the new instruction solves one problem by introducing another, which an isolated success would not show.
What makes improvement checkable
The essential comparison is between the current and proposed procedure on comparable inputs. A longer instruction document is not itself proof of better performance. It might add unnecessary work or make the important rule harder to discover. The quality needs to appear in completed tasks, not in the number of written requirements.
Our suggested practice is to make every change explainable in one sentence: which observed failure it addresses and when it applies. A separate record should identify the version used for a particular task. That makes later diagnosis more concrete and prevents every mistake from producing another broad rule with unclear boundaries.
SIExpo has not tested Brain’s automatic updates. The development is a described architecture for learning procedures from experience, with checks before changes take effect. It offers a practical personalization direction for agents, while leaving its value to be judged through subsequent outcomes rather than a promise that mistakes will never recur.