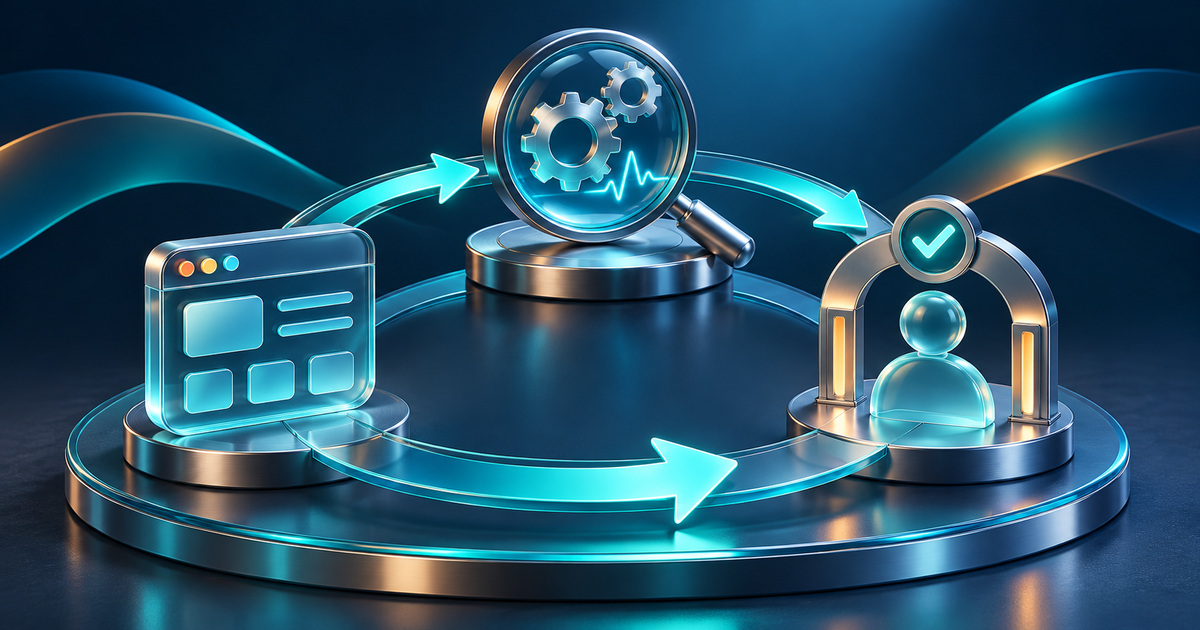
Google Labs announced Stitch Loop on November 18 as an experiment with a long-running product agent. It connects code and operational context, suggests improvements and prepares GitHub pull requests. Users review changes before merging. A global waitlist is open, with priority for eligible Google AI Ultra users; this is not confirmed immediate access for everyone.
After the first working version
The announcement draws attention to maintenance after launch. Software can compile while still having a difficult user journey, a slow operation or a component that is expensive to maintain. Building a first version and improving it subsequently require different evidence of success.
Our editorial interpretation is that a durable loop must connect observation, proposed change and verified effect. An agent optimizing a metric without context could improve the number while making the product worse. A shorter process, for example, is not necessarily clearer if it removes information needed for an informed choice. This is an illustrative risk, not a defect we have established in Stitch Loop.
A pull request needs an accountable reviewer
Human review is meaningful when a reviewer understands the objective and can inspect the change. We would expect a proposal to explain the observed problem, the assumption behind the fix and the acceptance criterion. An assertion that code has improved does not explain whether the right behavior changed.
A pilot could start with a limited component and a known task. That would measure not only code quality but also the time required for review. If reviewers repeatedly have to reconstruct missing context, work may have moved to another person rather than disappeared.
Product signals have boundaries too
Connecting logs and feedback should follow the actual permissions governing those records. We recommend defining which signals are needed and removing secrets and unnecessary personal information in advance. This is a design recommendation; we have not connected a product or tested an integration with Stitch Loop.
It also matters how a goal is declared complete. A useful check compares behavior before and after a change under equivalent conditions and leaves a route back. Otherwise continuous agent activity can be mistaken for continuous improvement.
The experiment proposes an interesting approach to work after launch. The verified result today is the announcement and open waitlist. Practical benefit, proposal quality and the real burden of review remain questions for future evaluation.