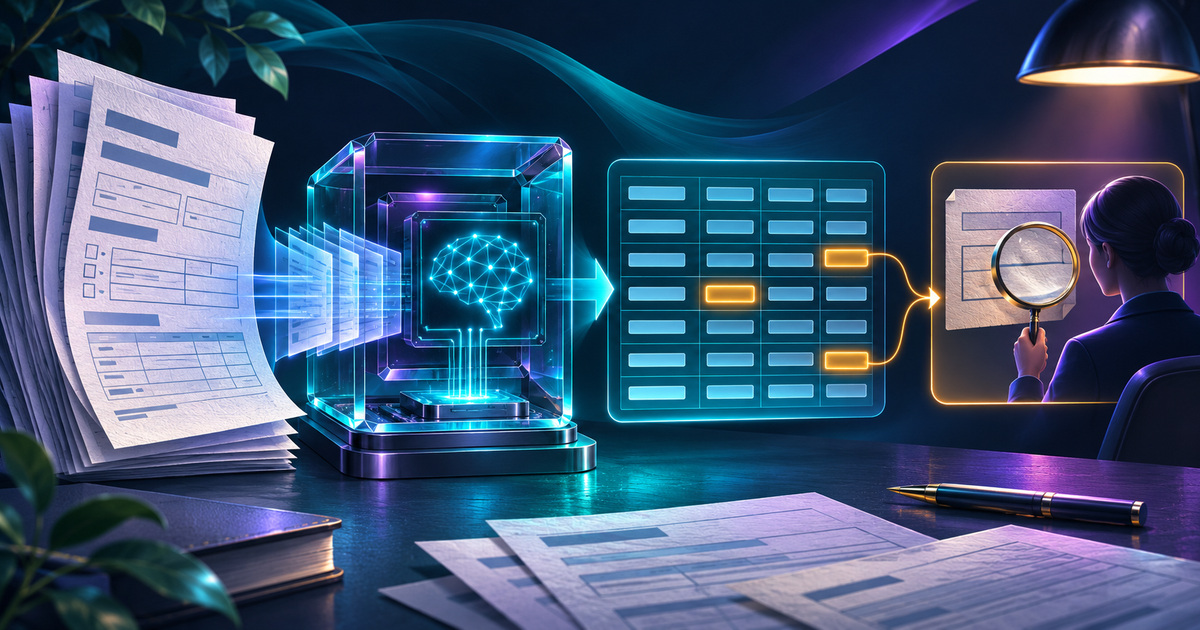
AWS announced a Textract Core agent skill on November 20. It selects the appropriate API and parses responses into ordered text and structured fields. The company says it handles multipage PDFs and flags less-confident results for review. There is no extra charge for the skill itself; normal Textract charges still apply. This is an integration layer, not a promise of free processing or processing entirely on the user's computer.
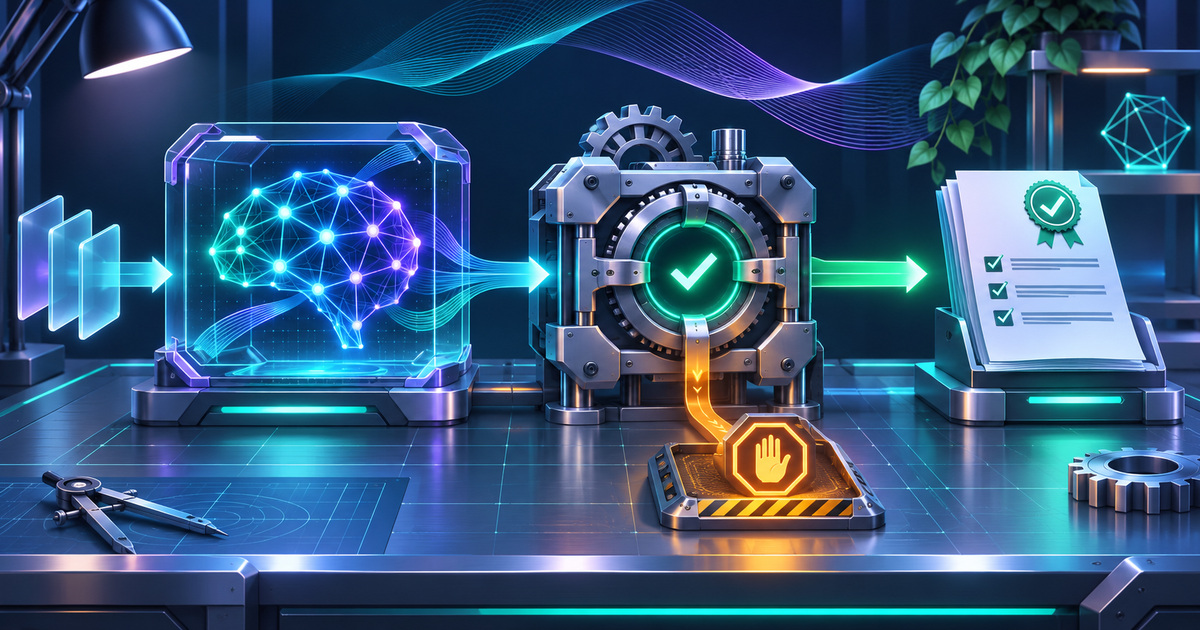
The important distinction is between asking an agent to read a document and invoking a specific extraction service. An agent can route the task while a parser turns the response into usable data. That structure does not yet establish whether a number is an identifier, an amount has the right currency, or a date has been interpreted correctly. This is our editorial assessment of the integration work that remains.
Textract's documentation lists six supported languages, without Bulgarian. It also discusses difficult tables, merged cells and unsuitable input quality. Accepting a PDF therefore does not establish that the system can accurately read a Bulgarian form. A selection process should check both the file format and the language scope of the particular operation.
A useful pilot would use a small set of documents the team is authorized to process, with expected values checked beforehand. Names, dates, identifiers and totals can be evaluated separately. This prevents strong performance on easy fields from hiding an error in the field that triggers a consequential action. It is a proposed evaluation procedure, not an experiment conducted by SIExpo.
Confidence also needs an application rule. One practical example is routing an uncertain value to a person together with its source page, rather than silently converting it into zero or an empty string. The threshold should be chosen for the task and the data. A convenient percentage is not a universal guarantee of correctness.
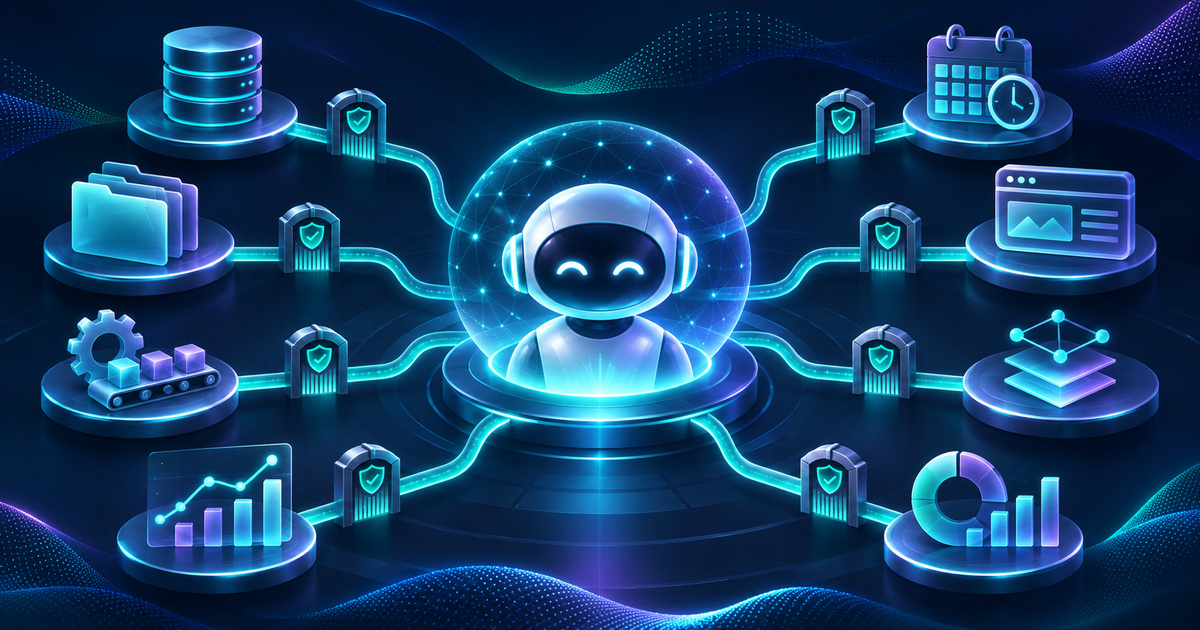
The official Agent Toolkit for AWS describes how tools, skills and plugins fit into an agent workflow. Its availability is not an independent audit of this particular parser. Before deployment, a team should identify the version, document-access boundaries and the way results reach the next system.
The useful boundary is between extraction and action. Structured fields can become a draft record, while validity checks, duplicate handling and acceptance rules remain explicit. The verified development is a shorter integration path. Accuracy on an organization's own documents is still a subsequent question, and this article does not claim that measurement has already been performed.