The AFFECT preprint, submitted on November 19, examines a basic problem for robotics world models: whether their predicted future changes correctly when the action changes. Authors John Won, Yonghoon Dong and Jinwoo Shin propose an auxiliary training objective matching the effects of action perturbations.
On DROID, they report that the correlation between success in the model and on the real robot increases from 0.47 to 0.79. That is a correlation, not a 79% success rate. The result comes from the authors and has not been independently reproduced by SIExpo.
Attractive video versus a useful model
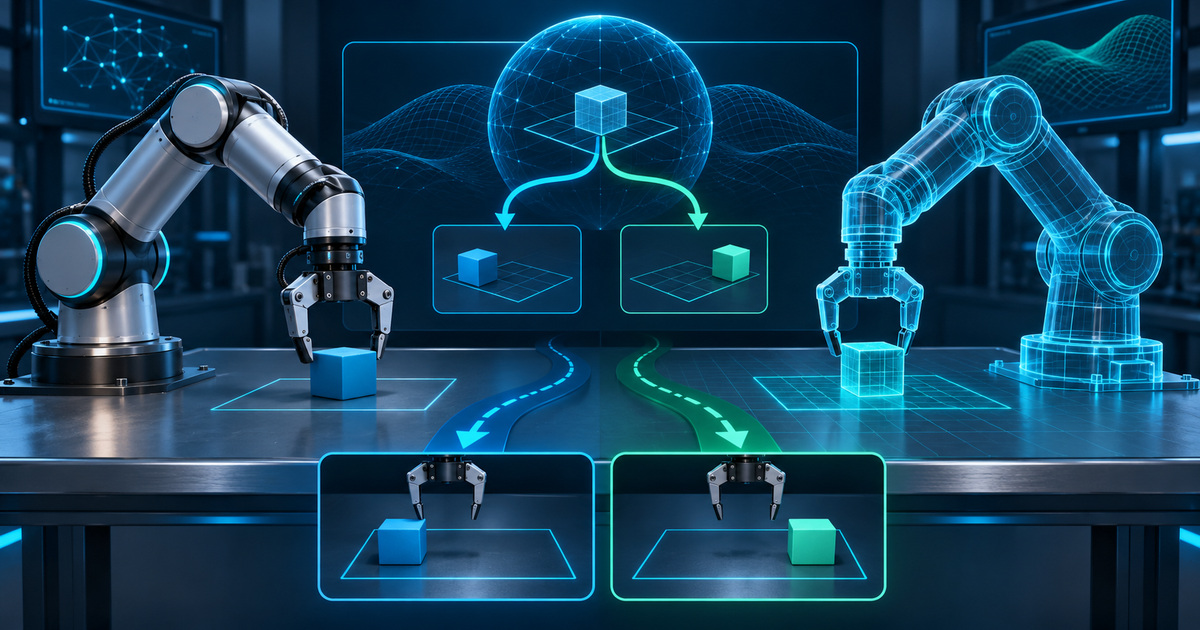
Our interpretation is that simulation for action selection has a different job from a visual demonstration. When two similar movements have different consequences, a planning system needs to preserve that distinction. Otherwise, it may prefer a convincing prediction that does not help make the actual decision about what to do next.
A proposed example is grasping an object from two slightly different positions. An assessment could check whether the model distinguishes expected displacement from loss of contact. This illustrates an acceptance scenario, rather than an experiment conducted by SIExpo. It does not establish that the particular method solves every case of that kind or generalizes to unfamiliar objects.
Limits of the evidence
The full paper discusses limitations involving observed features and finite samples. A test can evaluate only effects captured by its representation. The abstract and full text belong to one study; they are not two independent confirmations of its result. Keeping that distinction visible avoids overstating how much corroborating evidence is available.
For a separate evaluation, we would distinguish visual quality from usefulness in selecting actions. One check could examine how plausible predicted frames look; another could examine whether the ranking of suggested actions matches measured outcomes. A strong result on the first axis should not automatically transfer to the second, because they support different operational decisions.
From a preprint to a system
A pilot needs a safe execution boundary and a separately verifiable success criterion. Controlled examples with known conditions and consequences could come first. Only then would there be grounds to expand task variety. This is an editorial proposal for evaluation, not a reported deployment or a validation of safety-critical use.
AFFECT poses a useful question for the sector: how do we establish that a simulated future carries information about the action being selected? Its reported result supports a specific research direction. It is not a universal guarantee of physical accuracy, safety or readiness for an autonomous robot to operate in everyday environments.