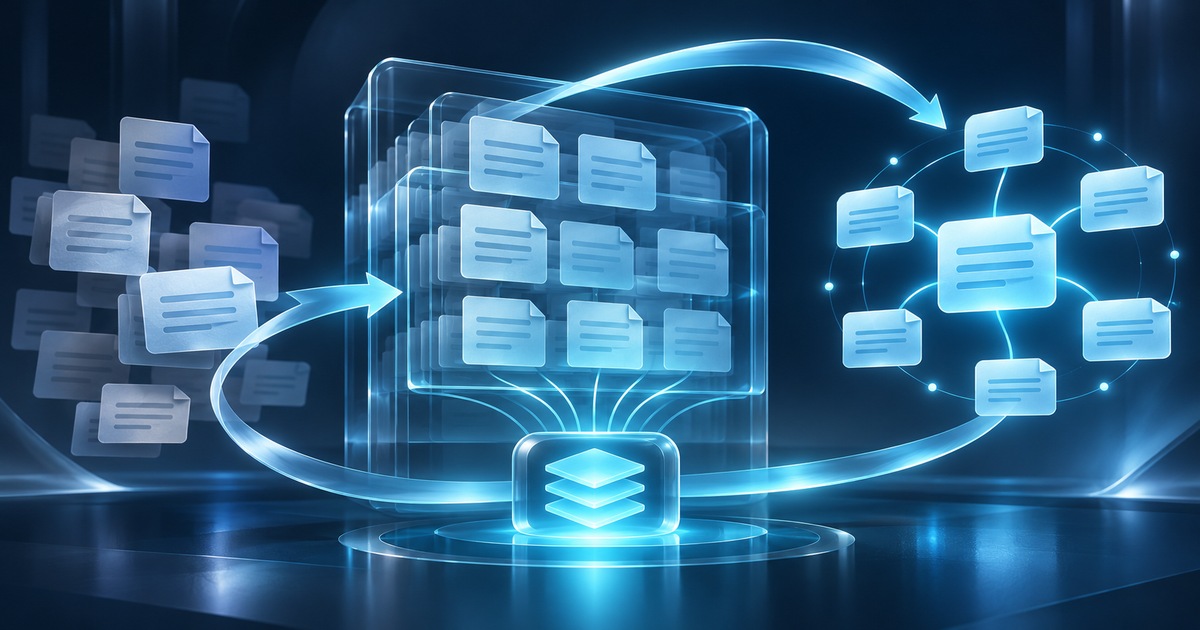
On November 6, 2026, Anthropic published an engineering account of Claude memory: taking notes while working, then reviewing logs in a process called “dreaming.” The approach aims to correct mistakes and organize information for future sessions. Its reported evaluations are company experiments; they do not establish general reliability for every agent or task.
What can be used in practice
The separate Dreams documentation describes a research preview requiring an access request. A job takes an existing memory store and between one and 100 past sessions. It produces another store for review before use, preserving the input. Processing is asynchronous and billed at the selected model’s standard token rates. The documentation explicitly says the service is not eligible for Zero Data Retention. That matters when deciding which logs to include.
Memory stores address another part of the problem: where persistent notes live. According to the documentation, they contain workspace-scoped text documents accessible through the agent’s file tools. Every change creates an immutable version for auditing and recovery. Both read-only and read-write access are supported. Anthropic warns that malicious material from an external source could enter memory through prompt injection and influence future sessions.
Memory and a long conversation address different problems
The compaction documentation covers shortening accumulated conversation so work can continue within the context window. An application can request a summary, use a threshold to trigger compaction, or implement its own mechanism. Some options preserve recent turns verbatim. This manages available space in the current process; persistent memory also raises separate questions about access, updating and retention.
The background includes the April 2025 Sleep-time Compute paper. Its authors investigate processing context before a particular question arrives. On their modified mathematical tasks, the approach reduces computation needed at answer time for comparable accuracy. Its effectiveness also depends on how predictable future questions are. This is separate research with specific tasks, rather than independent confirmation of Anthropic’s new experiments.
Editorial interpretation: a note needs provenance
For a developer, a useful question is how an agent will distinguish a verified rule from a temporary hypothesis. A note saying that a test passed, for example, is useful only when its project version and supporting result are clear. When the code changes, the old note must be discoverable and open to revision.
A practical evaluation could compare an agent with and without memory on identical tasks, including cases containing outdated or contradictory notes. It should count the full cost of preparing memory, retrieving it later and reviewing its contents. These are our interpretations of the documented architecture, not reported production outcomes.
Access controls deserve equally concrete tests. A shared reference collection and an agent’s working notes do not necessarily need the same permissions. Reviewers should ask whether a mistaken entry can be traced, whether its earlier version can be recovered, and whether another session can encounter it before review. A successful answer on one task would not settle those questions.
A better-organized archive may make work easier, but the existence of an archive cannot establish the truth of its contents. Returning to the original log and recovering an earlier version are meaningful parts of evaluating this kind of system. The November post is useful as an engineering discussion when read alongside the actual product boundaries.