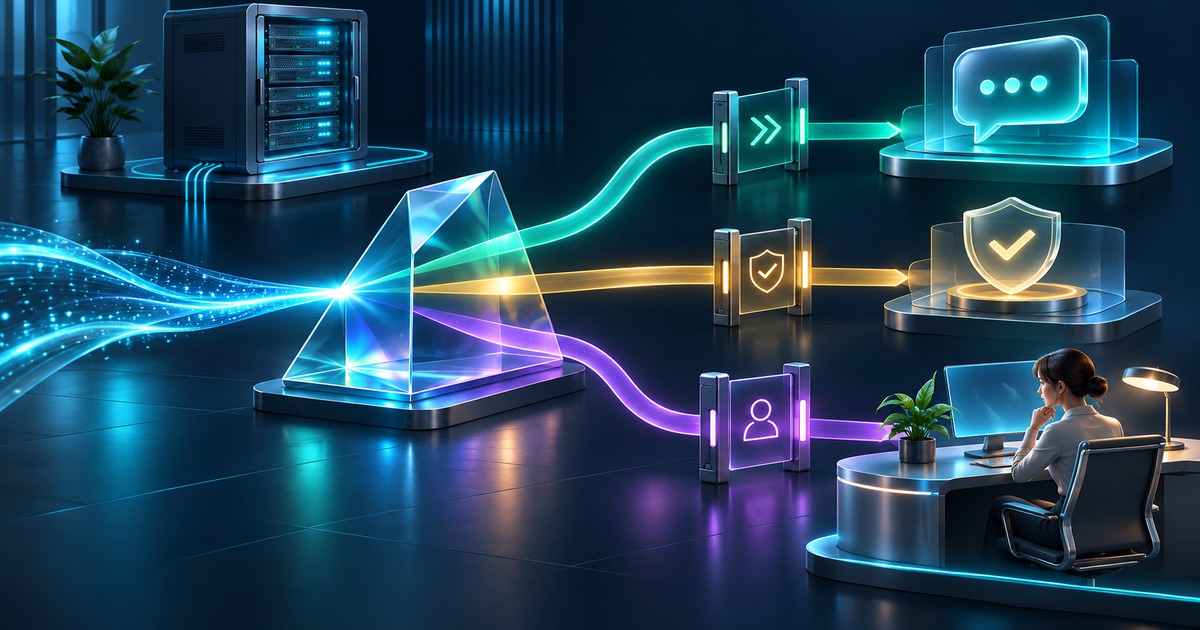
Norway's boost.ai announced Presis on November 10, 2026. The model handles classification around AI-agent conversations, including routing, question scope, and checks before an answer is displayed. The company says platform rollout continues over the coming weeks. This is a specialized layer, rather than an announced replacement for every generative model.
Answering and checking are separate jobs
The provider reports internal tests showing at least 2.5 times faster operation than the replaced models. This is a company claim, not an independently reproduced SIExpo result. Self-hosted in this description means infrastructure controlled by boost.ai, rather than automatically downloadable weights or installation on every customer's own server.
The LLM configuration documentation assigns Presis analytical work, including review and orchestration, without separate configuration when LLM features are enabled. Generative functions and selected external providers have separate settings. The page is marked as updated in October, so November's announcement does not establish the model's first appearance under this name.
Classification decides what happens next
Our editorial interpretation is that a conversation requires more work than producing an attractive answer. The system must decide which function owns a request, whether sufficient context is available, and when a person should take over. A mistaken routing decision can send an otherwise capable generative model down the wrong path.
Consider an illustrative customer asking to change contact details after several messages about a product. Routing only on the last word may miss the intention; following the previous topic too strongly may prevent the change of subject. This is a test-conversation example, not a Presis defect that we have discovered.
A useful evaluation would include clear requests, mixed intentions, and ambiguous messages. Each should have a defined acceptable response: automatic routing, a clarifying question, or human help. Aggregate accuracy should not obscure a small class of errors with substantial consequences.
The review should also separate an appropriate refusal from an unnecessary blockage. A classifier that declines everything could look cautious while making the service unusable. Conversely, forwarding every request might look responsive while losing the intended scope. Those are proposed comparison criteria, not additional measured claims about this product.
Fewer external dependencies does not mean no failures
Running a classifier on provider-managed infrastructure can remove one dependency on an outside model service. It does not follow that the entire application becomes immune to overload, software defects, or problems in another integration. This is a boundary of the architectural argument, not a report of an actual outage.
In voice support, we would measure time to a useful response across the complete conversational turn. Speech processing and the selected downstream operation also contribute. A faster intermediate classification cannot determine the final delay on its own. Comparison needs the same load and acceptable answer quality.
The documentation also distinguishes staging previews from live configuration. A team therefore needs to know which settings actually serve customers. A successful preview conversation is not enough evidence that identical behavior has reached production.
Presis is a concrete example of specializing models around an agent conversation. Its value should be assessed through correctly routed and completed tasks, human intervention, and total cost. A new name or a promised speed improvement does not replace that review.
Sources: boost.ai — Presis classification model announcement, boost.ai — LLM configuration and Presis analytical tasks. The cover is a conceptual AI illustration, not a documentary photograph.
Editorial verification: 2026-11-11T07:14:46.966546+00:00.