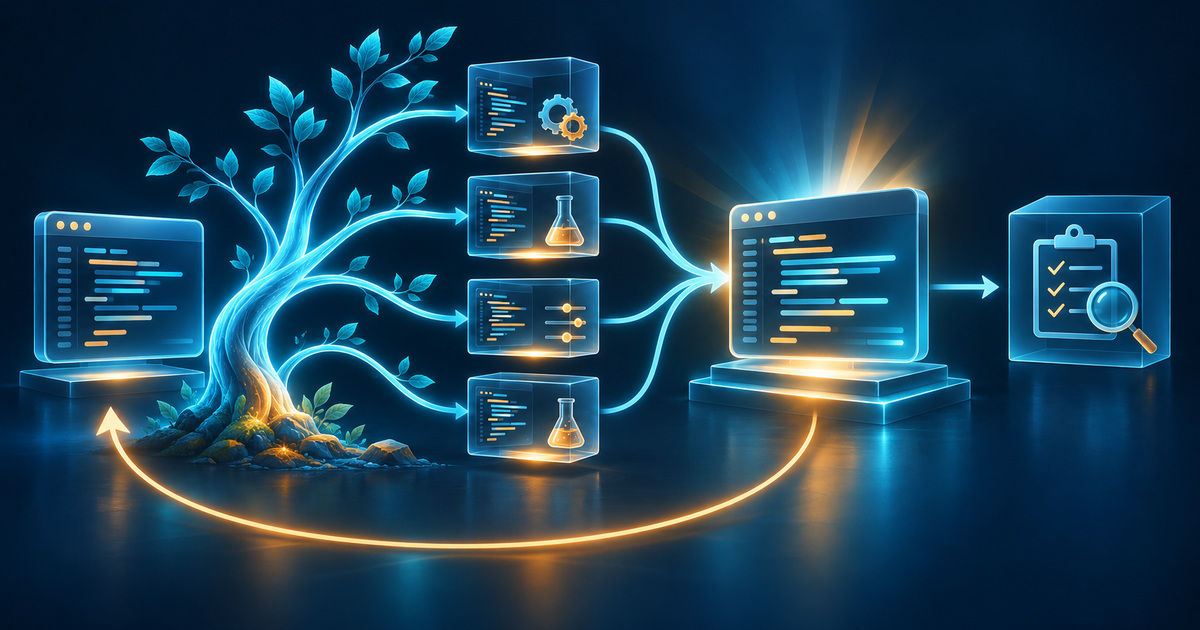
The November 16 preprint Evaluation-Free Recursive Self-Improvement for Coding Agents introduces Explore-then-Integrate, or ELITE. It develops separate implementation improvements from one parent and combines compatible mechanisms. Downstream task outcomes do not guide candidate selection inside that cycle; structural and operational validity checks remain. In their evaluation, the authors report an improvement from 60.0% to 85.6% on SWE-bench Pro under the tested configuration. This is an experimental author-reported result, not independent confirmation for every implementation.
What changes in the agent
A coding agent is more than its language model. Surrounding software organizes the task, tools and subsequent steps. Changing that program can alter behaviour without training new model weights. This research concerns agent implementation, rather than proving that a model creates a generally more intelligent successor in every domain.
Consider an editorial example with two proposed changes: one improves context gathering, while another changes how failed commands are reported. They might complement one another, but they could also assume incompatible interfaces. Combining them requires examining their interaction, not merely collecting textual edits. The example illustrates the engineering question and does not claim those exact changes were tested in ELITE.
This is an important distinction for anyone reading the term self-improvement. The object being improved must be identified. A program can become a more effective organizer of a fixed model while the model itself remains unchanged. Whether the resulting system generalizes to different work is a separate question.
Evaluation-free does not mean unchecked
There is a difference between executable software and software that solves more useful tasks. A structural check might establish that the required interface exists. An operational check might show that a short scenario runs. Neither automatically proves improved performance on an unfamiliar problem.
The separation between the evolution loop and final evaluation is consequently essential. A method can avoid repeated task-solving while deciding which changes to integrate, yet still need outcome evaluation to substantiate an improvement claim. The research title should not be interpreted as eliminating that responsibility.
What a practical comparison needs
For background, the SWE-bench project describes evaluation using real software tasks and tests executed in prepared environments. Results depend on the chosen tasks, versions and conditions. A benchmark name and a percentage therefore do not fully specify an experiment.
In a practical comparison, we would preserve the initial agent version, budget, model and tools. Changes could then be assessed on a separate set that was not used for tuning. These are editorial evaluation criteria, not additional findings about ELITE. They help distinguish a useful behavioural change from adaptation to one convenient test.
Repeated evaluation matters as well. If an initial and modified agent are each observed only once, differences in execution can be mistaken for stable improvement. A useful record should make the variation visible and retain failed attempts alongside successes. This is a proposed assessment practice, not a statement that the published work omitted it.
Compatible mechanisms can still carry costs
Adding a mechanism is useful only when its benefit justifies complexity. One change might reduce the number of steps while another increases preparation per step. Their combined value could depend on task length. Richer context could help one problem while increasing cost on another. These are analytical possibilities to measure rather than presumed defects.
A convincing report would consequently show more than a final score: which mechanisms survived, how they interact, and the cost of the complete improvement process. If the aim is to reduce inner-loop evaluation expense, the next question is whether that saving remains useful across tasks and repeated runs.
ELITE is interesting as a concrete alternative to choosing each candidate solely by its downstream score. The reported result supports a research direction, not unlimited recursive self-improvement. For builders, the actionable question is how the changed agent program handles new work with a known version, traceable modifications and a separate final evaluation.