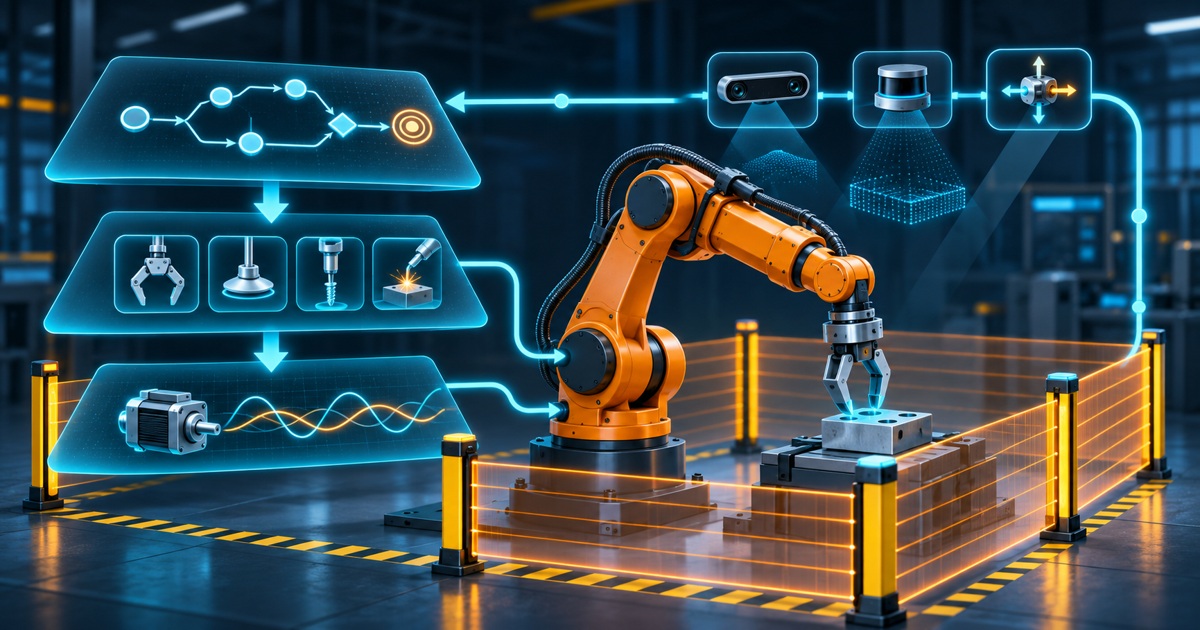
Grid Robotics published the Envisioning Agentic Robotics position paper on November 13. The authors distinguish general planning and verification, callable skills, and low-level body control. Their central proposal evaluates a robot as a closed loop of observation, action and outcome verification.
This is a conceptual framework and research agenda. It is not presented here as a newly available robot, an adopted industry standard or independently demonstrated physical autonomy. The authors themselves discuss limitations of existing evaluations and the gap between simulation and reality.
Who is responsible for the outcome?
A useful editorial distinction separates three questions: what the person wants, which skill to invoke and how movement is executed. A system can have a capable language component and a capable controller, yet connect them incorrectly. A claim of completion needs an observable result.
Consider our example of moving an object onto an empty shelf. Planning chooses the goal, a skill organizes grasping, and control executes motion. The system must then check the object’s location. If the shelf becomes occupied meanwhile, a previously sound plan is no longer sufficient. This is an explanatory example, not a SIExpo demonstration.
Time and memory are physical constraints
For a text answer, waiting for another reasoning step can sometimes be acceptable. A moving object or person does not pause while a model decides. Observations therefore need a clear time reference, and the system needs to recognize when old context is no longer dependable.
Memory alone is insufficient. A remembered location may support planning without replacing fresh sensor evidence before action. Similarly, a description of a tool’s behavior must remain distinct from the result actually observed after using it.
An evaluation should separate task success, safe interruption, recovery and execution cost. If the environment pauses while the system computes, that condition should be reported. If a person repairs the environment between attempts, that intervention belongs in the protocol too. These are our practical evaluation criteria, consistent with the paper’s concern about comparability.
Longer trials also matter. A sequence of individually successful actions can still fail to maintain a standing responsibility when objects move, priorities change or sensors become uncertain. A test should make those changes explicit rather than assuming that a one-off demonstration settles sustained autonomy. This is an assessment principle, not an additional empirical result from the authors.
SIExpo has not run a robot experiment and does not claim that the proposed separation automatically provides safety. The paper’s value is in asking more precise system questions: who verifies the outcome, what happens when evidence disagrees, and when a person must intervene. Answers require demonstration in a specific physical setup.
Editorial verification: 2026-11-17T07:54:00.882419+00:00.