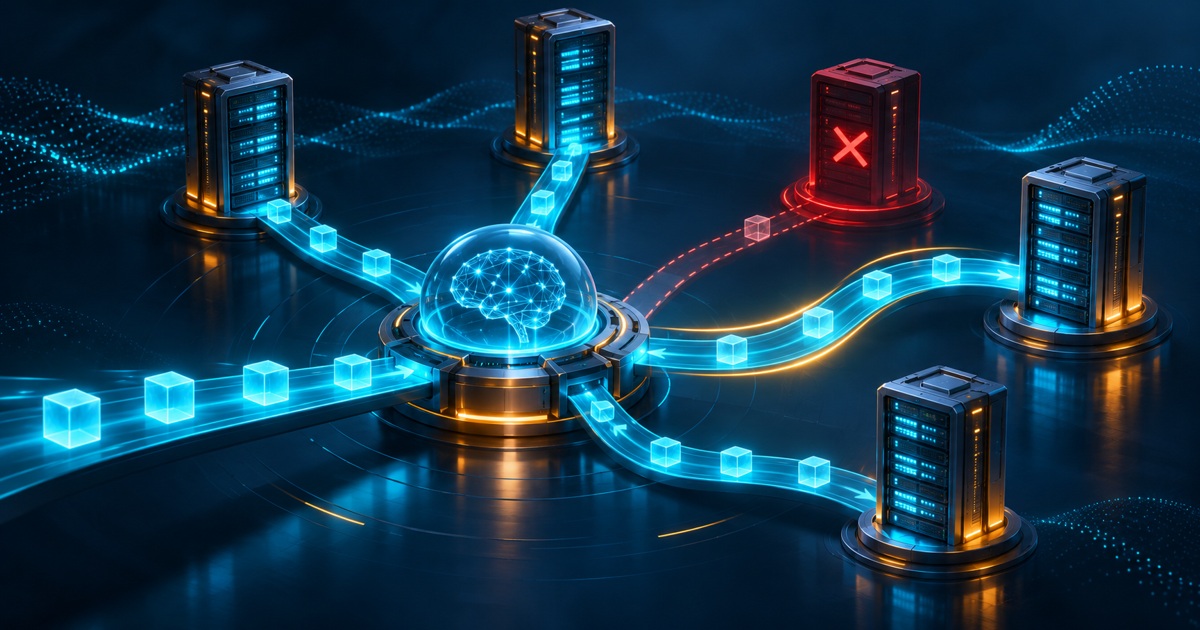
Hugging Face announced on November 16 that language requests through Inference Providers are moving to OpenRouter’s routing infrastructure. The service is intended to choose a provider according to current conditions and try another when one fails. This changes the service infrastructure rather than introducing a language model.
Existing applications need to notice a practical compatibility detail: custom API keys for language providers no longer operate in the previous way, and these requests are billed through Hugging Face. The announcement distinguishes this route from image, video and audio processing. The change should not be assumed to apply identically to every platform task.
A familiar interface is only one contract
Our editorial assessment separates the convenience of a common API shape from the system’s operational behavior. An application can send familiar fields while receiving output from a different infrastructure provider. A migration check should therefore trace the selected provider and final outcome, rather than merely confirming that the SDK returned no error.
Consider an internal assistant for company documents. Automatic fallback can be useful for public text. Where processing agreements constrain data handling, the permitted provider set becomes decisive. This is our deployment example, not a report about a particular customer or a discovered compliance failure.
The prompt-caching documentation also explains why sessions deserve attention. Reuse of a common prefix is separate from an application’s semantic memory. A cache should not become an assumed durable store for important conversation history, or proof that a model has correctly remembered a fact.
Measure the benefit in the application
SIExpo has not made paid inference calls for this report. A useful evaluation would compare identical inputs before and after migration: first-token latency, completed streams, valid tool arguments and spending per accepted result. A successful short chat does not cover a broken stream, timeout or provider behavior under load.
Cached and uncached prompts deserve separate measurements. Mixing them into one average can attribute a gain to routing when the actual cause is prompt reuse. Similarly, a lower list price does not necessarily reduce total spending if retries increase.
For a production team, a small representative test set is more informative than an isolated speed demonstration. Include a structured-output request, a long input and an intentionally unanswerable question. Record failure handling as well as successful answers. These are proposed acceptance criteria, not measurements attributed to either company.
The practical significance is easier access to models served by outside providers. Open weights alone do not mean local execution. Teams still choose acceptable routes, manage spending and determine whether an answer completes the real job. The vendor’s routing-performance claims remain company claims rather than an independent SIExpo benchmark.
Editorial verification: 2026-11-17T07:54:00.882419+00:00.