A company environment built for evaluation
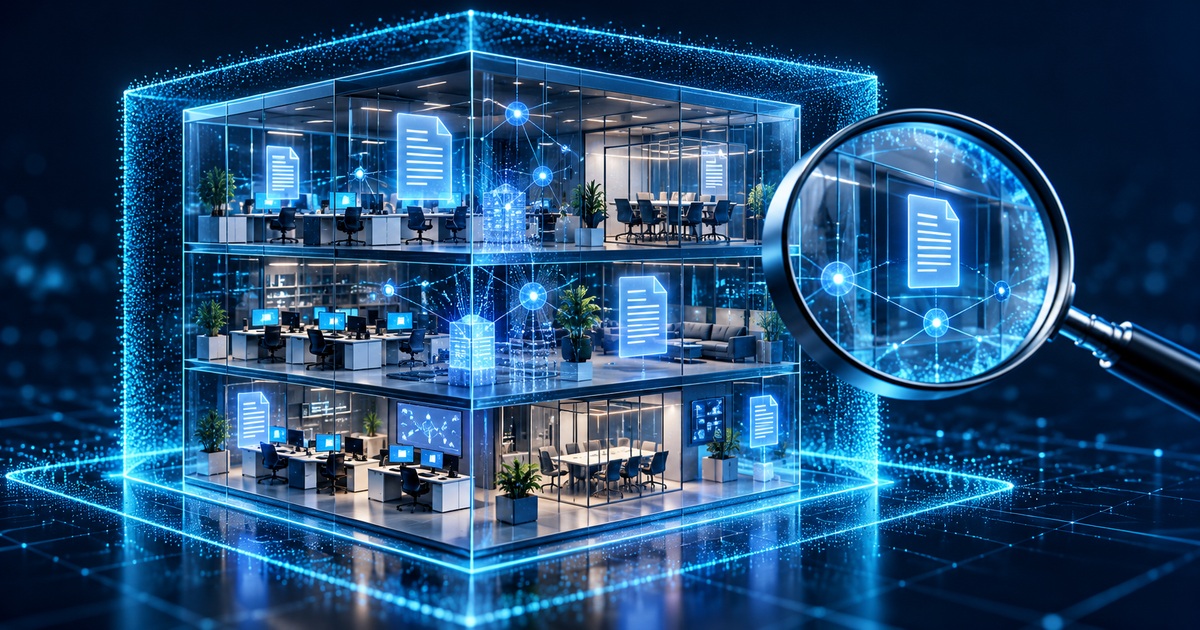
On October 30, Microsoft Research described Industry Evaluation Data Generation Platform, an approach to evaluating Copilot in synthetic organizations. The environments contain invented roles, documents and communications rather than real customer workspaces. This is an account of internal evaluation infrastructure, not an announcement of a freely downloadable dataset for every organization.
According to the authors, public information including O*NET helps make occupational roles plausible. O*NET does describe occupations, tasks and work requirements. That makes it useful background for designing scenarios; it does not independently establish Copilot's quality.
Why one correct answer is insufficient
Consider an editorial example: an employee asks who should approve a project change. In a short test, returning the correct name may be enough. A more realistic history could contain an old message naming one approver and a subsequent decision naming another. A useful system must distinguish current information, its source and the limits of its confidence.
The situation can be modeled without genuine names, customer agreements or private email. The advantage is experimental control. Evaluators know which decision came last and can change one detail at a time. Changing dates, questions and organizational structure together would make differences in the outcome harder to explain.
This scenario is our interpretation of the evaluation problem, not a reported experiment or a measured accuracy result for the product.
Reading internal results carefully
Microsoft reports internal measures of the generated environments' quality. Measuring synthetic data and measuring answers delivered to actual customers are different activities. We therefore do not turn an internal improvement into a promised accuracy gain for every user.
Useful questions include how expected answers are established, which failures count, and whether identical tests are repeated after model changes. It also matters whether the evaluator is independent of the system that generated the test cases. Without those details, a plausible fictional company can still conceal easy or repetitive tasks.
The evaluation set should challenge missing evidence and conflicting records, not just reward fluent answers. Reporting an aggregate score without explaining these situations makes it difficult for a prospective user to decide whether the test resembles their own work.
A practical interpretation for smaller teams
A small developer does not need Microsoft's scale to adopt the principle. Our editorial recommendation is to start with an invented project, a few roles and verifiable conflicts between old and new documents. Each question should have a success criterion written in advance, including when refusing an answer is appropriate.
The next stage is a limited pilot using authorized data and human review. Synthetic tests support repeatability, but cannot automatically demonstrate fitness for a different language, organization or workflow. The development is better evaluation infrastructure; confidence in a particular deployment still requires its own evidence.