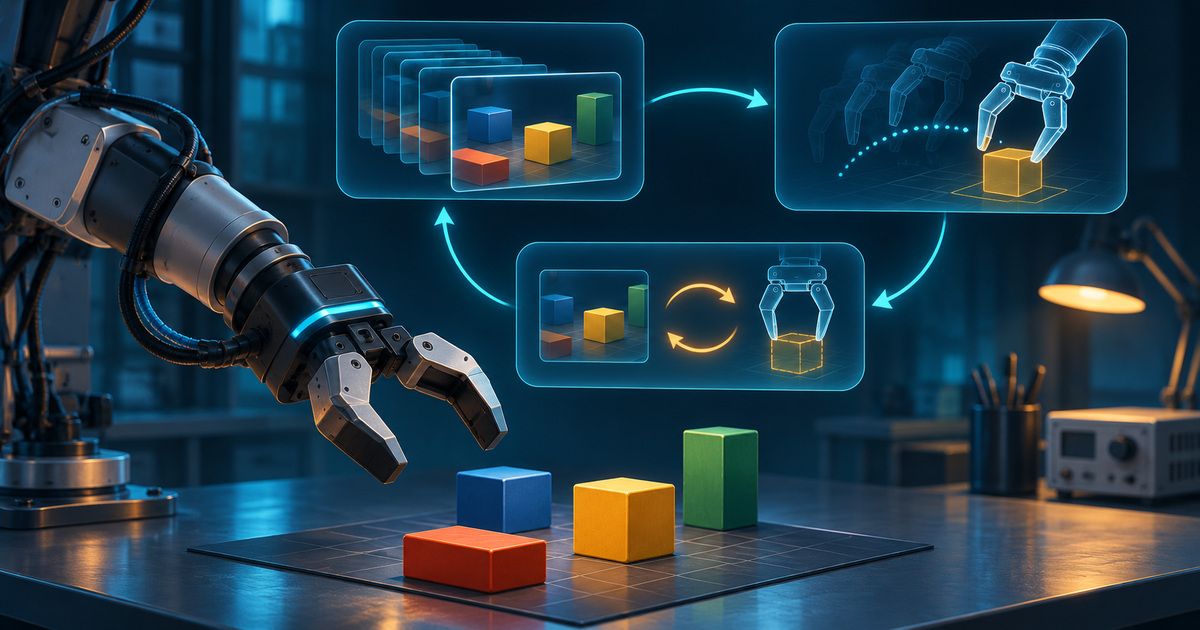
The November 19 Mind2Act World preprint proposes a more diagnostic way to evaluate robotic manipulation. Rather than measuring only final success, it separates reasoning from previous observations, accurate execution and the composition of both through feedback. The authors describe 30 simulated tasks and 180 configurations. In their evaluation, the strongest agent succeeds in only 12% of combined tasks. That is a result for the tested benchmark and systems, not a score for robotics as a whole.
What a single score hides
Imagine a robot that must select the correct box and put an object inside. Several failures can produce the same unsuccessful outcome. The system might forget which box was marked earlier, position its gripper incorrectly, or fail to revise its plan after the object moves. This is our example of the diagnostic logic, not a specific task claimed to appear in the benchmark.
A single aggregate result cannot identify which cause matters. Separated tests can help explain why improving a language-level description does not necessarily repair contact motion. Conversely, a more accurate controller cannot restore information already lost by the planning system. Developers need to locate a failure before deciding which component to change.
Planning and control are different layers
For technical context, robosuite's documentation describes controllers that translate actions into robot control. Depending on the controller, commands concern positions, velocities or other controlled quantities. A textual instruction and an executable movement command are consequently different representations of a task.
In the box example, choosing a destination is a logical decision. Approaching with the gripper and maintaining suitable contact are movement problems. Observing whether the object actually arrived connects the two layers. An evaluation needs that connection rather than assuming that a convincingly described action has already been completed.
This distinction also clarifies why a natural-language plan may be easy for a person to understand while remaining incomplete for a machine. The plan leaves implementation choices to a lower layer. Those choices still have to work under the observations and constraints available during execution. Better wording alone cannot establish that they do.
Feedback creates an additional challenge
Consider an object that shifts after initial contact. A fixed sequence could continue toward the old position. A feedback-driven system needs to recognize the changed state and decide whether correction is necessary. That requires more than acquiring another image: the new information must influence the next useful action.
Testing individual skills does not settle this issue. A robot may distinguish objects and execute a familiar movement but struggle when it has to switch between these capabilities during one task. This makes combined tests valuable for agent evaluation. The relationship between components is itself behaviour that needs to be tested.
For an illustrative evaluation, a team could preserve the observation before contact, the command it issued and the observed result. Comparing those records would distinguish an incorrect destination from a correct destination reached with a failed movement. These are editorial assessment suggestions, not experiments performed by SIExpo or additional reported findings.
Reading the benchmark responsibly
Start with the environment. Simulation supports organized comparisons, but does not automatically capture every property of real materials, sensing and mechanics. A simulated study can reveal an important problem without certifying readiness for a warehouse, home or factory.
Then ask how failures are categorized. A useful report should let an evaluator check whether a component change corrects a particular failure or merely moves the difficulty elsewhere. A higher total score can be informative, yet a diagnosis explaining the changed behaviour is more actionable for engineering.
Mind2Act World is interesting as an attempt to make these distinctions visible. Its message is not that individual capabilities lack value. Their composition has its own difficulty and reliability. Strong follow-up results should show both improved outcomes and the specific connection between memory, decisions and actions that became more dependable.