On November 7, 2026, OpenMOSS published a technical account of MOSS-Live, a realtime conversational system combining voice, visual context and tools. The service has a documented November 2 snapshot, so the new article should not be read as evidence that access began only on November 7. This report concerns architecture and evaluation, rather than a new hands-on SIExpo test.
Two different operating timescales
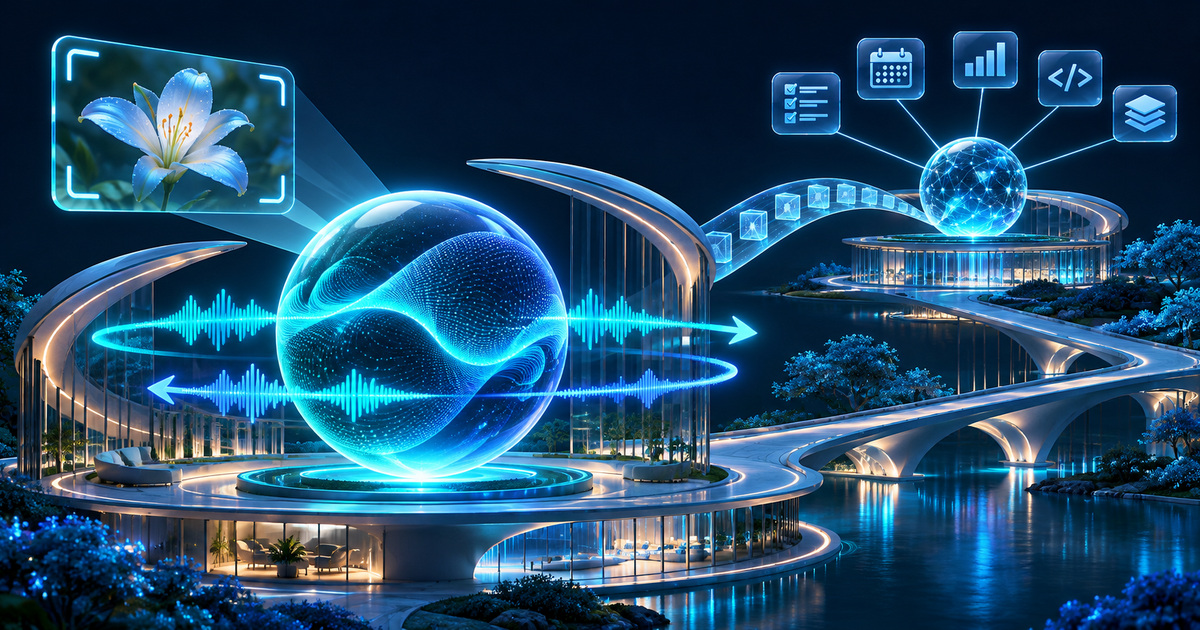
The team describes a foreground model for perception, speech and turn-taking, plus a background model for reasoning, tools and longer tasks. A coordination layer shares memory, context and task state. The aim is to keep conversation moving while requested work is still running. Demonstrations come from the developer rather than independent field trials.
In its published comparison, MOSS-Live scores 51% tool-use success on FDB v3 and 57.93% multi-turn task success on τ-Voice. The first is tied for highest and the second ranks second among compared systems. These are not universal rankings or guarantees for every request. We select these two figures because conversational quality and task completion are different measurements.
Documentation provides a WebSocket interface for a two-way session, streamed audio and visual frames, and streamed responses. It lists stable ID moss-live-1.0 and dated snapshot moss-live-1.0-2026-11-02. Complex tasks can be delegated to an application's own backend. The public repository explains architecture and demonstrations; its existence does not itself establish released weights for running the complete model independently.
Editorial assessment: an interruption must reach the task
The most interesting practical test is what happens after intent changes. A person might request options for an event on one date, then change the date while a search is still running. The voice layer can acknowledge the correction correctly, but the background result also needs to be recognized as stale. Otherwise, a fluent conversation can deliver a persuasive answer to a canceled question.
A useful test would record the task version when each search starts and check whether the result returns to the right version. Separately, examine whether an interruption stops only speech or also an action already underway. These are our proposed criteria, not documented MOSS-Live guarantees.
Distinguishing an acknowledgment, a new command and a side conversation also affects privacy and accuracy. A real pilot needs to consider language, noise, latency and participants' consent to microphone or camera use. A smooth demonstration does not replace evaluation under those conditions.
The technical publication supplies a concrete architecture and measurable results for discussion. It illustrates why the next challenge for voice agents is coordinating conversation with action; individual scores must be read alongside methodology and verification limits.
Editorial verification: 2026-11-09T07:12:30.497786+00:00.