NVIDIA and Japan's Elith have presented Nemotron-Personas-Finance-Japan, an open synthetic-persona dataset for developing and evaluating AI in financial applications. The team's announcement is dated November 9, 2026; the dataset card identifies version 1.0 with a November 10 creation date. These are different editorial and product records, not a reason to invent a single release timestamp.
The central aim is to let developers test conversations and user scenarios without moving genuine customer files into an experimental environment. A simulation dataset is importantly different from a register of actual people. The authors explicitly describe the content as artificially generated, even where the narrative descriptions resemble realistic life stories.
Understanding the scale
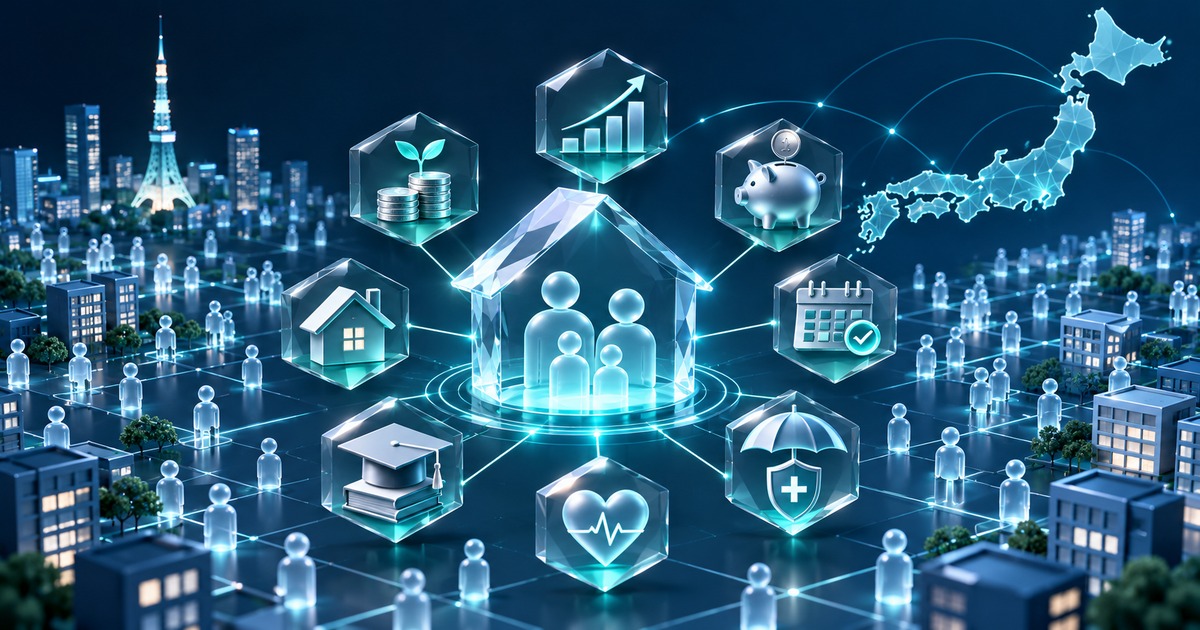
The card lists one million rows, each containing nine different persona descriptions. That produces nine million role descriptions, not nine million independent real customers. There are 50 fields combining narrative personas, attributes and contextual information. Contextual dimensions include households, employment circumstances, geography, financial assets and digital habits.
The profiles are written in Japanese and designed around Japan. They are not a Bulgarian population sample and should not be represented as a statistical description of Bulgarian consumers. Translating the text would not, by itself, change the demographic assumptions on which the dataset was constructed.
The authors ground generation in official demographic and labor statistics, using tools including NeMo Data Designer and probabilistic graphical models. This provides an inspectable starting point for the profiles. It does not mean that each fictional biography has been observed in reality. Matching distributions and establishing the truth of an individual record are different tasks.
Limitations belong with the data
The card describes specific independence assumptions among variables, including the treatment of occupation and education when location and sex are given. The dataset covers adults only. Its authors also acknowledge limitations in the available statistics concerning sex and gender. These notes matter in evaluation because a fluent conversation can obscure an incomplete model of the population.
There is also a distinction between dedicated name fields and names appearing inside persona text. The public card says separate first-name, last-name and synthetic-address fields available in another distribution are excluded. Names can nevertheless appear within descriptions. Summarizing this simply as a dataset without names would be inaccurate.
The release uses CC BY 4.0 and is identified as available for commercial and non-commercial uses. Work with the data should reference the particular card and version rather than only the broad Nemotron name. Attribution and licensing information remain part of handling a copy or adaptation.
Useful tests and unjustified conclusions
An editorial example of an appropriate pilot would test whether an assistant explains the same financial term clearly to several fictional users. Another would present an ambiguous question and check whether the system asks for clarification. These are evaluations of interface behavior and responses, not decisions about an actual person's eligibility.
It would be unjustified to infer that strong performance on these personas establishes accurate credit assessment or suitable investment advice for real people. Publication of a synthetic dataset does not establish either result. Such claims would require separate evidence, methods and validation for the intended deployment.
When comparing AI versions, keeping the scenario, expected behavior and error definition fixed is useful. Otherwise, an apparent improvement could arise from changing the test conversation rather than the model. This is an editorial recommendation about experimental design; SIExpo has not conducted its own financial benchmark using the release.
The most practical value is a more explicit, inspectable test population for a particular language and context. Its usefulness depends on asking the question it was designed to help answer. Treating a realistic fictional user as a measured real customer would discard the distinction that makes synthetic testing valuable in the first place.
Sources: NVIDIA and Elith announcement, dataset card and data, CC BY 4.0. The cover is an original AI illustration of synthetic personas, not a photograph of actual customers.
Editorial verification: 2026-11-10T08:20:59.808167+00:00.