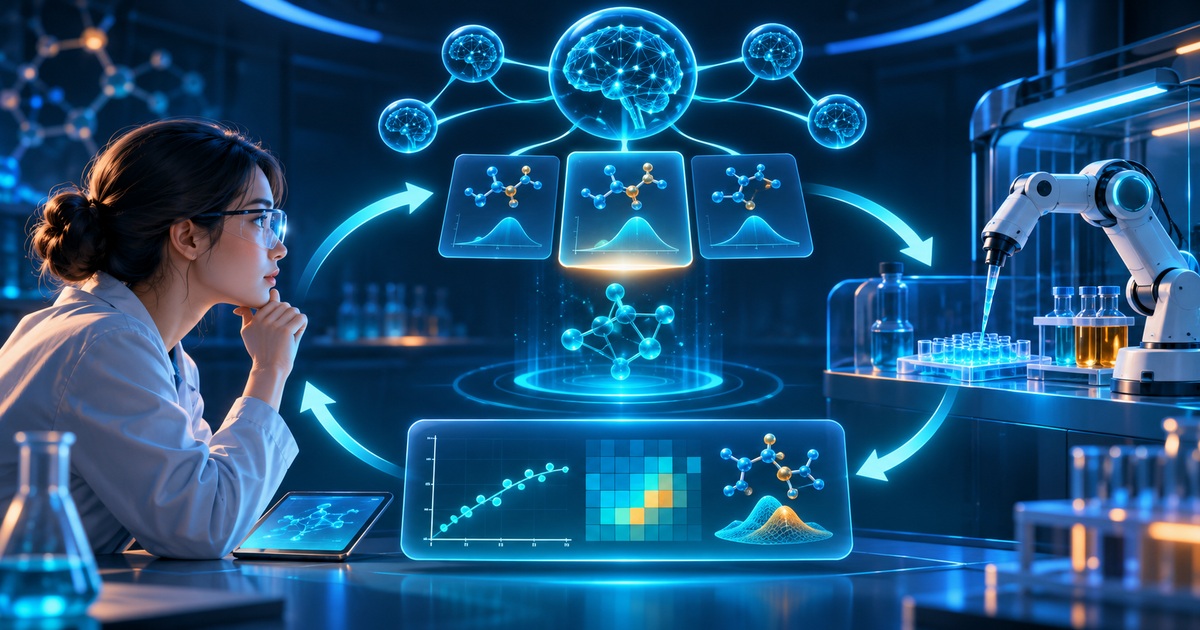
Perplexity announced Frontier Research on November 16. The initiative aims at systems that formulate and test scientific questions. The company states support from more than 10,000 GPUs and an intention to publish models, data, code and research. This is a research program rather than evidence of a completed general-purpose automated scientist.
The official site groups the work into six areas: multi-agent orchestration, pre-training, continual learning, reinforcement learning, systems and evaluations. Its research journal supplies the date.
The different evaluation question
Our editorial assessment is that a scientific agent should be judged by verifiable new knowledge it helps produce. A long answer with many references can be a valuable review. It is not, by itself, a new experiment or an explanation that survives an attempt to disprove it.
For example, an illustrative materials-research system might propose a hypothesis, specify which measurements would support it and revise its conclusion after a negative result. That is an example of an acceptance criterion, not an outcome achieved by the announced program.
Such an evaluation needs to preserve the decision trail. Which source suggested the question, which assumptions were added by the model and which measurement changed the answer? Without those steps, a person can receive a persuasive account without a way to examine its foundations.
Multiple agents do not guarantee independent evidence
Splitting work between several agents can be a sensible design. One might search, another plan an experiment and a third criticize the argument. But if they all accept the same mistaken premise, increasing their number does not make the conclusion more reliable. This is a general editorial consideration for evaluation, not an observed weakness of a particular product.
A useful future test would include questions whose answers are not known beforehand and clear rules for permitted tools. Failure should be recorded too: when does the system acknowledge that evidence is insufficient, rather than continue producing explanations?
Cost also belongs in that assessment. An answer obtained after many attempts should be compared with the complete search process that produced it. Otherwise a successful final demonstration can conceal the resources needed to reach it. Again, that is a proposed evaluation principle rather than a reported result.
The initiative matters because of its resources and explicitly stated scientific ambition. Its promised open outputs should make that ambition assessable in more concrete terms. For now, the accurate news is the start of a research program, not the completed automation of scientific discovery.