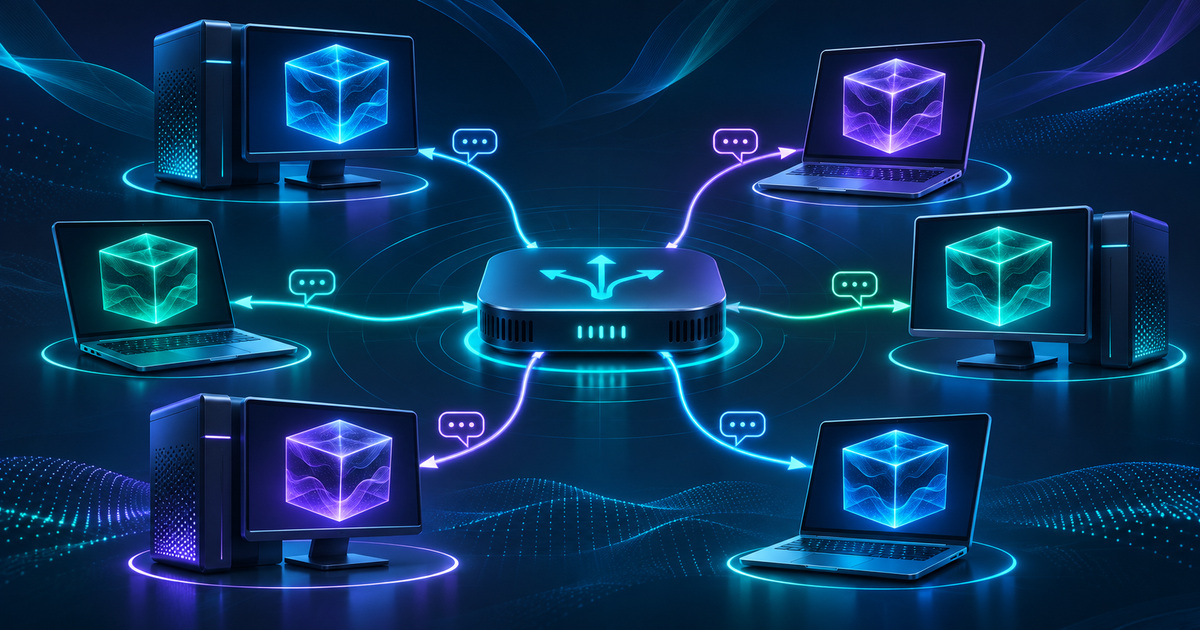
Basecompute described Superfluid fleet mode on November 20, presenting local language-model serving through one endpoint. The central idea is replication: each machine holds a complete model copy, while a router assigns whole sessions. It does not pool several computers' memory to fit a single model that none can run alone.
The authors report an experiment with six machines and 64 simulated users. These are the authors’ measurements, not an SIExpo benchmark. We do not transfer the numbers to arbitrary models or networks. The reported node-failure recovery is likewise a demonstration, not an availability guarantee for another deployment.
The problem replication addresses
If one machine already fits a chosen model, additional suitable nodes can serve different conversations. If the model fits nowhere, adding more such replicas does not solve that initial problem. This distinction matters to teams considering a shared local service built from several spare computers.
The official repository describes compatible APIs and multiple supported runtimes. A compatible endpoint can simplify client integration, but does not establish identical behavior for every option, tool format or streaming detail. Acceptance work should therefore include the exact requests an application uses.
A useful pilot would compare one machine with a small fleet using the same model, inputs and output limits. Time to first token, answer duration and failed requests could be measured separately. Concurrent-user count should be recorded because an empty-queue result does not describe a busy service. This is a proposed test plan, not an experiment we performed.
Local deployment also has access boundaries. Operators need to know which machines may join, where conversations are retained and who controls the shared entry point. Being on a local network does not automatically make every participant trustworthy. These choices need their own operational review.
The verified development is the described ability to distribute sessions across complete local replicas. Its practical value depends on workload and available devices. The difference between more conversations served and a larger model in pooled memory remains the most important condition for reading this announcement correctly.