AWS announced AI data preparation capabilities in SageMaker on November 17: synthetic-example generation, dataset evaluation and transformation, auto-labeling and human review. Access is through the Python SDK or a coding assistant equipped with the relevant skill. The announcement specifies general availability in Northern Virginia and Oregon. That does not establish availability in every AWS Region.
Labeling and checking are separate jobs
Documentation clarifies that this preparation path handles text data and has regional and resource constraints. It describes managed jobs and SDK requirements. Service selection should begin with the dataset's format and purpose, rather than simply whether a workflow can be expressed in natural language.
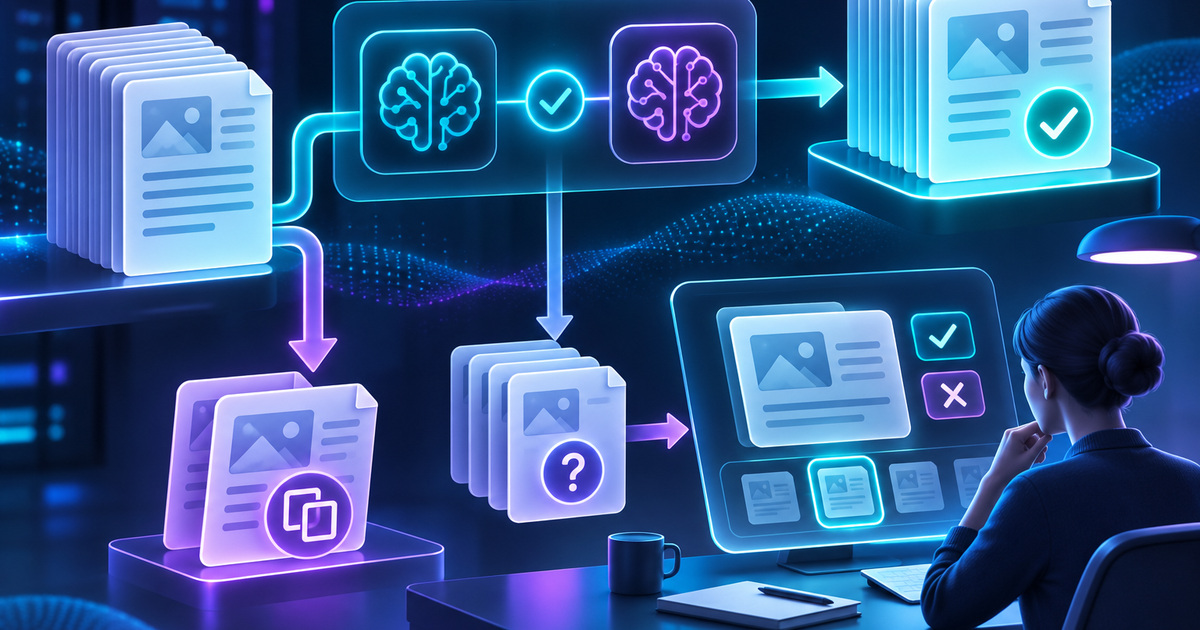
Our analysis starts with a basic distinction: several models can agree while making the same mistake. Agreement is useful for prioritizing review, but it does not replace a reference label. An acceptance test should therefore compare against human-checked examples that were not used to tune the labeling rules.
Make uncertainty actionable. A reviewer needs to see the source, proposed label and reason for escalation, rather than receive only a confidence number. The outcome of that review should change a traceable record, so a later evaluator can distinguish original machine labels from corrected ones. This is a proposed workflow, not a claim about a measured SageMaker deployment.
Documentation specifies SageMaker Python SDK version 3.30.0 or newer and notes that most jobs invoke Bedrock models. Applicable invocation quotas and charges therefore belong in the budget. Data preparation does not mean free generation of unlimited datasets.
Keeping evaluation independent
In an example support-center task, we would split materials by source or product family where many near-identical document versions exist. If almost identical records enter both training and testing, evaluation can look strong without demonstrating generalization. This is an editorial example of overlap risk, not an observed SageMaker defect.
For synthetic data, preserve the specification, source context and reason for each validation rule. An incorrect template can then be traced to its origin instead of turning into thousands of apparently independent examples. Generated row count measures volume, not diversity by itself.
Human review has its own cost
Measure how many disputed examples a reviewer can resolve and how often rules need clarification. If much of a dataset requires rework, automation may move effort to another stage. That outcome has to be measured for the particular task.
The tools may reduce manual assembly of separate preparation steps. Quality remains a property of the complete process: sources, criteria, independent evaluation and corrections. SIExpo has not created a dataset with the new service and does not present company examples as its own practical test.