AWS announced on November 17 that SageMaker HyperPod Inference supports NVIDIA Dynamo. The integration targets large models and distributed request serving. AWS describes multi-node operation and separate worker pools for processing input context and generating responses. This is a product capability; the provider's published measurements are not a universal acceleration guarantee.
Two different parts of one request
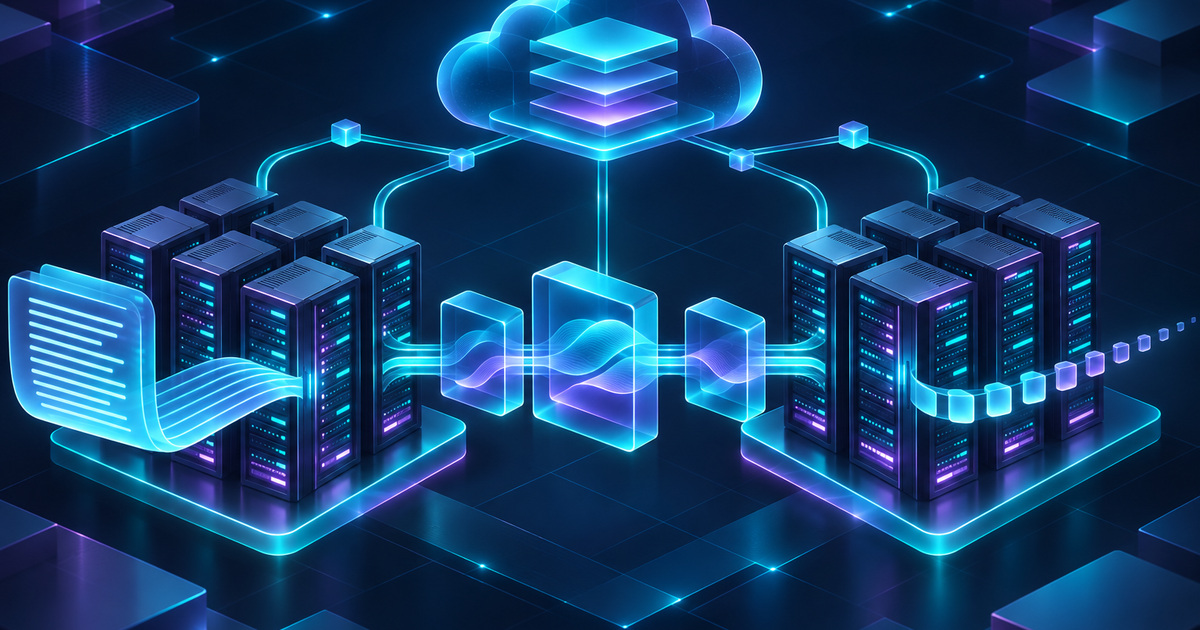
Input context must first be processed before the model generates subsequent tokens. AWS documentation distinguishes an aggregated mode, where workers handle both phases, from a disaggregated mode with separate pools. In the latter, KV cache moves between them. Dynamo's own documentation describes the distributed-serving framework; it supplies technical context rather than independent verification of a particular cloud result.
The useful engineering question is whether those phases really have different profiles in your traffic. A short question following a long document can load a system differently from a long answer with little input. Separate pools allow the phases to be considered individually, while introducing coordination and state exchange.
Documentation exposes the choice through dynamoSpec in the endpoint configuration. Managed components include operators and scheduling for related GPU work. This separates serving configuration from model weights; the service does not automatically select the most suitable model for an application.
Cache must arrive on time
Our reading is that the network becomes part of the computation path. A faster worker for one phase does not guarantee a faster final response if transfers or waiting on another pool dominate. We would therefore observe queues, time to first token and complete response time together.
For a pilot, retain the baseline configuration and compare identical requests at the same quality level. Break down results by input length, output length and concurrency. An average alone can conceal infrequent but severe delays that shape the user's experience.
Include failure recovery in that comparison. A useful evaluation asks what happens to an active request when a worker becomes unavailable, which state is retained and how the application recognizes a failed or repeated response. These are proposed operational checks, not findings of failure in HyperPod.
Managed operation still requires choices
Teams still choose the model, worker-pool sizes and target behavior under load. Check current documentation for available regions, compatible runtime images and settings. A demonstration configuration should not be transferred directly into a production process, and no single cost outcome applies to every workload.
The development puts more orchestration behind a managed integration. Whether disaggregation helps must be established using complete requests and actual service constraints. SIExpo checked the announcement and documentation without deploying or benchmarking a cluster.