On November 2, 2026, Taiming Lu, Qi Xu, Zhigang Hua and Zhuang Liu published a preprint on arXiv describing Strategist. The system uses an AI agent to write and test programs that control how language models solve tasks. The researchers keep the tested programs in a shared library so that later tasks can reuse earlier work.
What changes
The same language model can be asked a question once or called several times. The surrounding software might request two independent solutions and inspect where they disagree. The choice of procedure can therefore change both answer quality and execution cost. Strategist leaves the model weights fixed and changes the code that organises model calls.
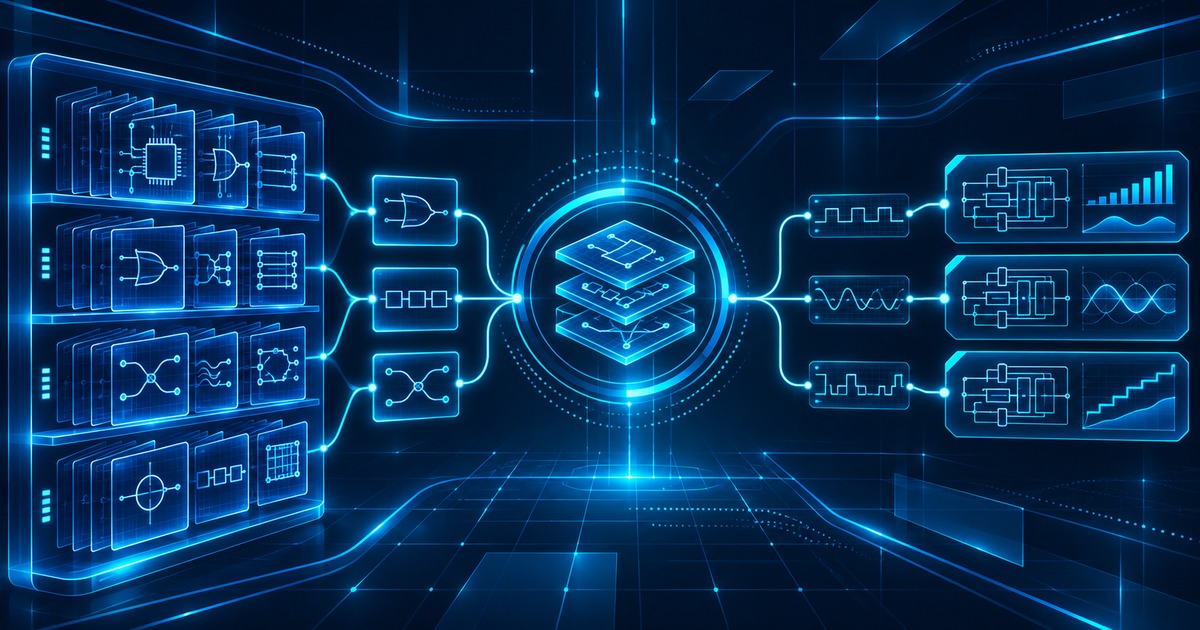
At the start of a search, the system receives a task and development examples. It retrieves relevant programs from the library, generates candidates, runs them on examples and compares the measurements. Candidates can call previously created programs through a shared interface. The library retains measurements and testing notes, including for candidates that did not win. A later search can start with an idea that has already been tried.
The earlier DSPy project also explored automatically optimising programs that use language models against a chosen metric. Strategist focuses on how executable strategies can be saved and composed across tasks. Both provide context for the broader question of how to measure and improve the software that surrounds a model.
How to read the numbers
The authors compare the system on 30 benchmarks and report average accuracy of 74.7%, compared with 74.0% for the reference approach. They also report a 39% reduction in average weighted execution cost. Under the study’s definition, Strategist wins on 24 benchmarks. The definition allows a cost win at similar accuracy, so 24 wins do not mean the system was more accurate on every one of those benchmarks. The paper also identifies tasks for which costs rose or savings came with an accuracy trade-off.
The search itself has a separate cost. For an example benchmark with 100 rows in each development split, the researchers describe about 20,000 candidate-by-example executions for a full search. The 39% lower cost of running a discovered strategy therefore does not measure the full cost of finding it. If a task runs many times, cheaper future executions may pay back the search. At low volumes, the up-front cost may exceed the savings.
The researchers also test retrieval of existing strategies for ten held-out benchmarks and transfer to other models. Those experiments show how the team tested reuse within its setup. The work is a preprint. Before applying the method to a specific system, a team would need to measure total cost, accuracy on its own tasks and the behaviour of generated code under the access restrictions in that system.